Repository navigation

Replies: 12 comments 32 replies

|
Hello @MorenoMdz 👋 Thank you for providing a detailed description of the issue you are facing. 🙏 Can you check if the timeout errors go away if you use Node v16? It can help in confirming if this issue was indeed caused by the upgrade.
Based on my understanding, the number of active connections can change based on the number of incoming requests and the number of concurrent requests your application is handling at a time. If there's a sudden surge in incoming requests, your application will try to open more connections to the database to handle these requests, which can cause the connection limit to increase.
If your server only has 2 cores, then having a connection limit that's too high could potentially lead to resource exhaustion on the server. Can you try enabling metrics and check if any connections stay idle?
The number of connections allowed by your PostgreSQL server (or pgBouncer) should be configured based on your application's needs and your server's resources. There isn't a one-size-fits-all number for this. So, I think tweaking max connections number and timeout should be a good next step. |

That was my assumption as well, but doesn't that looks weird when the error says "limit", if the limit is dynamic it is not really a limit?
The DB server in this case right? Not the NestJs server as this one dynamically scales up and down. I am having some issues wrapping my head around the idea of 5 connections (2 cores * 2 +1) in the pool would be enough for for example a spike of 100 connections.
Right now it has the defaults, which for the connections limit seems to be dynamic so I am not getting the reason to manually edit it, more info about it is welcome hehe On the timeout I think I will try with 20s for now, is that reasonable? |
|
Sorry forgot the big question. Yes we tested in Node 16 and it does not crash. |

|
So with Node 16 everything works, but the exact same setup with Node 20 crashes? And that is reproducible? |

|
Yes, might be able to scope it down to a single service running one of the endpoints that has this error, I will see if I can put some time to get this in a repo over the weekend |
|
On the "crash" part, is it expected to have the server crashing with an unhandled exception due to a max connection limit? |
|
That is up to you. Prisma just throws an error message that you can handle in your application. If you don't do that, depending on your framework and setup, that might crash the server, yes - but that is the same for any exception then, no matter if from Prisma or your own code. |

|
Hey @MorenoMdz. Let's start with the simple question:
The connection limit is either set via the And now:
What does
I assume this means that your app is configured to potentially use 15 instances of these Starter/0.5 core services if needed, so your app could potentially run 15 times?
Ok, so you have a PgBouncer that is configured to offer 33 connections to your apps maximum, correct?
What does that mean, I have not found anything googling for "Prisma Service package".
So your database server has 2 cores and allows maximum 31 connections?
Yes, increasing the pool timeout should allow more queries to be successful at the cost of worse UX of your app - waiting for 20s in a request is not a great experience. But you get less of those errors hopefully until we figure out what is really going on. Generally, a connection pool timeout error message means that on one server (instance), the Prisma Client connection pool could not give a new query a connection to be executed in the connection pool timeout of 10s. This happens when the pool was busy running other queries all that time, either because there were just too many queries, or the queries were too slow - or of course because the connection could not be opened in the necessary time. Right now the numbers above do not make sense to me. 17 or 33 connections per server, 15 instances, would mean many more potential database connections (33*15) than what I understand your PgBouncer and database to be configured (~30). I will need responses from you to these questions before we can continue. How much traffic does your app serve? |

The number from the error message is per instance, not across all the instances. Prisma Client runs on each instance and opens a connection pool with x connections each time. You can see the connection pool size when you enable logging and debugging, and then start you app - it logs the number of connection it starts the connection pool for. If that is 17 or 33, the instance you are running on is reporting 8 or 16 CPUs to Prisma Client.
Yes, but I was specifically asking for the Prisma Client queries. I assume 1 request to your app creates multiple calls to Prisma already - and that is a relevant number to know to be able to understand what "90 requests per minute" can lead to.
The timeout would affect all queries being executed on a saturated instance, you are probably just mainly seeing this one because it is the most common query you are running a lot maybe? Please take another look at my post as well, there were a few questions you did not answer. In such situations it is essential to have a full picture of what is going on. |
Yes this service uses the starter service with 0.5 cores and can scale up to 15 instances, so up to 15 apps running connected to the same DB server using pgbouncer. The max number of instances we have over the past day was 6.
We are using this NestJs package
It looks the DB server not got a heavy load, CPU over last day: 
RAM over the last day: Our errors in the same period: |


|
Ok. So you need to configure your database and PgBouncer in a way that the number of allowed connections is lower than the sum of all the connection pool limits all your PrismaClient instances running in your app. That could for example mean:
This way, if all 15 instances are turned on, and all use the full connection limit of the pool, it will still fit the limit of PgBouncer of 160 (probably 150 in use, with a few to spare - always good). And then PgBouncer will use the maximum 100 connections of the database probably to get the most value out of this. And then you can see what is really happening: Right now I think your setup is the wrong way around, with Prisma potentially using many more connections in total than PgBouncer and the database even offer. That should in theory lead to a different error than the connection pool limit ("out of connections"), but 🤷 That is super hard to debug what is going on. Let me know how this turns out when you change the configuration.
What do the red and blue lines mean? |
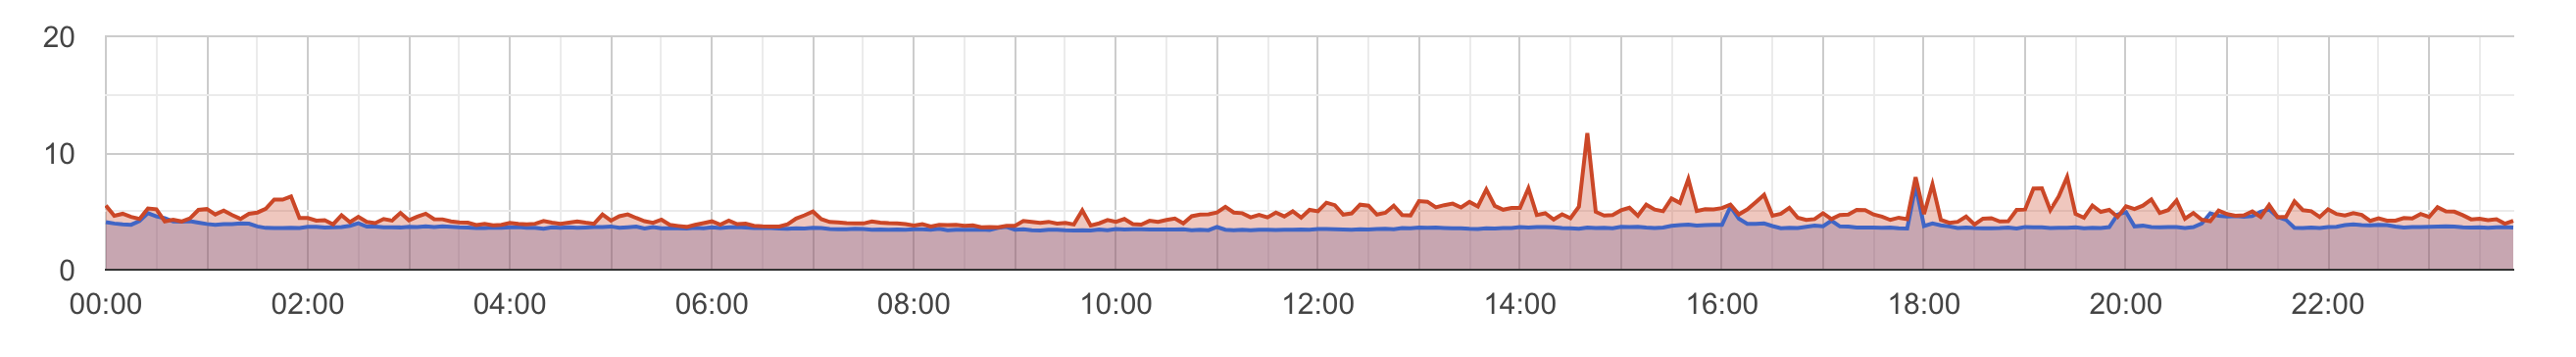
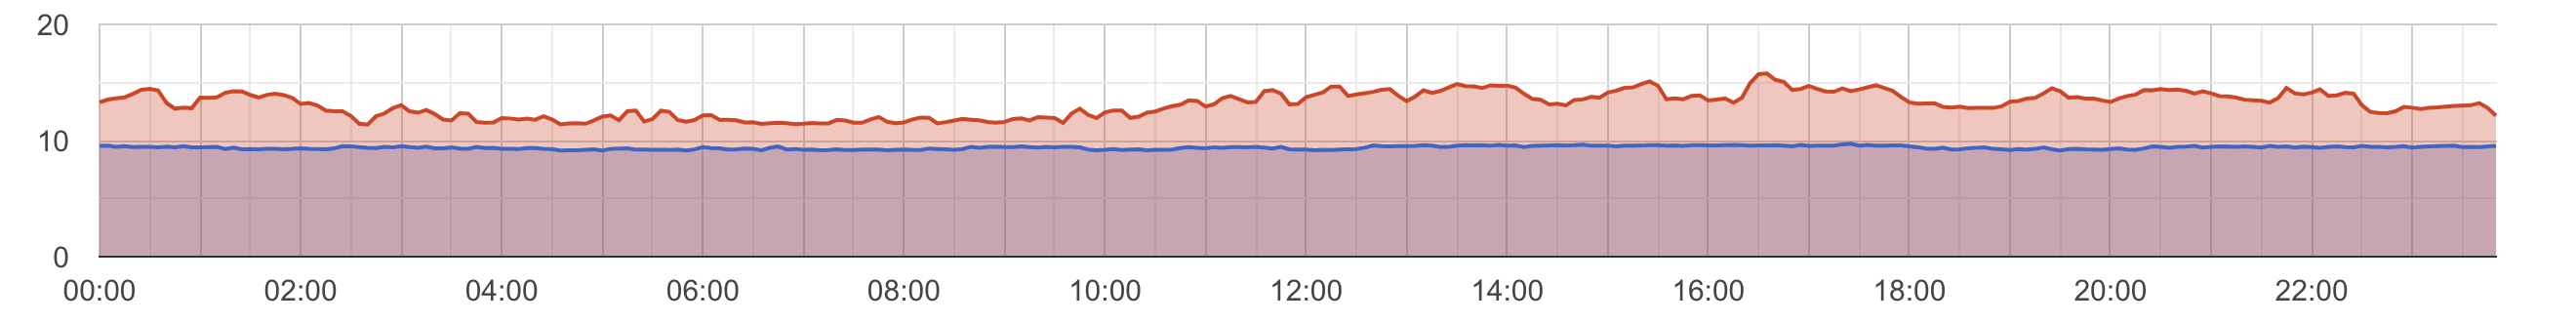
Resource % usage, the red one is the active instance and the blue ones are the read replica. This might be slightly more helpful, data over the past month from DataDog from the PG metrics, nothing out of the ordinary, the higher usage zones are due to organic traffic we had, let me know if you notice anything different. One thing we did yesterday was upgrade our server to use Prisma 5.1, it seems to have fixed this issue so we can probably checkmark this one as complete and recommend using the latest version. There was a small hiccup in how the IN queries work in Prisma 5.1 but unrelated to this issue. That said, there is still the problem of the number of connections reported by Prisma, I am going to do a few things to fully understand what's going on:
For a bit more context, this was the query that was showing the error most of the time: const data = await this.prisma.event.findMany({
where: {
userId,
shift: {
companyId,
},
status: {
in: [
status.ToDo,
status.InProgress,
status.OnBreak,
status.Complete,
],
},
},
orderBy: [{ shift: { startTime: 'asc' } }],
})On the number of connections topic...
Good info, but then that goes against the recommended cores*2+1 formula in the pool config, setting up the pool to 160 connections sounds very intuitive IMHO but doesnt follow the recommendation, so you can see how this can get confusing 🙃 Also, thank you very much for all the info and feedback so far 👊 |

No, what the error message is reporting is the connection pool limit. This is set when Prisma Client is started and does not change, and does not depend on how many connections are open or how often Prisma is started. Each number you see in this error message is from exactly one Prisma Client instance running in one app. As I described before, each instance probably runs its own Prisma Client instance with its own connection pool.
The formula is not the recommendation to be used with production traffic, but a default that Prisma can calculate and use. It is impossible for Prisma to know what your traffic and your application requires, and what your server and database can deliver - so this is always only a starting point. (If that is not clear enough in some documentation, please let me know and we can get that fixed!)
You're welcome! |
|
One more question, for this case where we have a shared core, if we wanted to test a connection limit, should I try with 2? As 0,5 * 2 + 1 = 2? Would that be a max number of 2 connections per instance of our server? |
|
I don't know what "a shared core" means really, and how that influences the performance. I would watch the actual CPU usage to define if it is too much or not. Generally the default formula is just that - a default. You can to define the number of connections in the connection pool (the limit) based on the CPU usage and the actual needs of your application. If it wants or needs to run 50 queries at the same time, 2 available connections mean that 48 always have to wait. If your queries are not the fastest, the queue easily can take 10s to be emptied - and then one of those queries would get that error message again. |
|
We are not seeing this error now when running with Node 20 and Prisma 5.1, I will mark this one as a potential solution for now but ill try to investigate more the issue. |
|
I decided to re-open this one, as this problem seems to be related to the way Nest/Prisma detect the number of available CPU cores. |

|
Yes, I suspect that too. |
|
@janpio got and update from Render:
Does that mean Prisma might be reading the number of available CPUs incorrectly? |
|
That is one way we could state it, or we would say that Render is reporting it incorrectly 😆 Fact is, the default connection pool size that Prisma is using is based on incorrect information. We'll have to investigate that together with Render. Thanks for sharing. |

|
Thank you for checking that, let me know if there's anything I can do to help. |
|
Did you also get an explanation why the server sometimes reports 8 cores (connection limit 17) and sometimes 16 (connection limit 33)? Generally, the "high" connection limit for the pool size did not actually cause you any problems. If Prisma had received and used the |
|
Just got it:
|

|
Also seeing similar issues. Not exclusive to the latest version of Prisma (v5.1.1), but also the last v4 release. We've been testing on Node v20 and recently downgraded to Node v18 in case there may have been stability issues there. We're also running on Render, although across different environments (one with more CPU and memory, and one with less) and that doesn't seem to make a difference. Steps we've taken so far:
The thing is, we're seeing these connection pool timeouts happening with fairly low traffic. It generally gets triggered when there's a burst of traffic, but nothing that should overwhelm the number of connections set in the connection limit (e.g., we set the limit at 30 and get a burst of 30 requests). Maybe there's an issue with how the connection pooler recycles connections and makes them available. I do see there were issues with this in the past. |
|
No, the CPU count is just used to set the default connection pool size. You could also manually set it to any of these values and it should work. If you do so, and have the same problem, and can reproduce it, we can look into that. But we need to be able to see the problem to understand it. |
|
@janpio going back to this, it seems the issue is the |
|
If you want to test Prisma, without |
Locally it seems to work fine, I have contacted Aiven and they are going to test and upgrade their servers with the new version and I will test it more by them and report here. Did Prisma 5.4.1 change anything in relation to this? |
|
Not that I am aware of, no. |

|
I have the same problem when running in a github action. Locally, it works just fine. There are 10 connections in the pool. Timed out fetching a new connection from the connection pool. More info: http://pris.ly/d/connection-pool (Current connection pool timeout: 10, connection limit: 10)
at _n.handleRequestError (/__w/orm-benchmarks/orm-benchmarks/node_modules/@prisma/client/runtime/library.js:122:6927)
at _n.handleAndLogRequestError (/__w/orm-benchmarks/orm-benchmarks/node_modules/@prisma/client/runtime/library.js:122:6235)
at _n.request (/__w/orm-benchmarks/orm-benchmarks/node_modules/@prisma/client/runtime/library.js:122:5919)
at async l (/__w/orm-benchmarks/orm-benchmarks/node_modules/@prisma/client/runtime/library.js:131:9116)
at async Promise.all (index 18)
at getRowsWithRelations (/__w/orm-benchmarks/orm-benchmarks/src/prisma/benchmark-pg.ts:[57](https://github.com/alfateam/orm-benchmarks/actions/runs/9796288292/job/27050384191#step:6:58):5)
at benchmark (/__w/orm-benchmarks/orm-benchmarks/src/prisma/benchmark-pg.ts:28:5) {
code: 'P2024',
clientVersion: '5.16.1',
meta: { modelName: 'Order', connection_limit: 10, timeout: 10 }
```bash |
|
I tried with pool size 2 in github action - and it worked. https://github.com/alfateam/orm-benchmarks/actions/runs/9804768733/job/27073137829 |
|
Pool size 3 also worked fine in github action. |

|
Hi there, To keep our discussions organized and focused on the most relevant topics, we’re reviewing and tidying up our backlog. As part of this process, we’re closing discussions that haven’t had any recent activity and appear to be outdated. If this discussion is still important to you or unresolved, we’d love to hear from you! Feel free to reopen it or start a new one with updated details. For more details about our priorities and vision for the future of Prisma ORM, check out our latest blog post: https://www.prisma.io/blog/prisma-orm-manifesto. Thank you for your understanding and being part of the community! |


Uh oh!
There was an error while loading. Please reload this page.
Question
We started getting A LOT of pool timeout connection errors from Prisma since our last release yesterday. The release was basically some unrelated changes and upgrading the versions of the Node in our NestJs server from 16 to 20.
The errors look like this, 90% of the time from the same query:
But they also show with a different limit
Info:
Our server runs on a Render.com service that has a (0.5) half core configuration, and can scale up to 15 instances.
It connections to a Postgres pgBouncer that is set to 33 connections (15*2 + 1). Prisma is running using the Prisma Service package with default settings.
Questions:
How to reproduce (optional)
It happens randomly over the day, we can't tie it to a specific behavior yet.
Expected behavior (optional)
No response
Information about Prisma Schema, Client Queries and Environment (optional)
// Add your schema.prisma and relevant query codeAll reactions